The first proof run looked great and was lying
AlphaForge P6 · 2026-08-23
AlphaForge is Clay's GTM engineering cohort. Each numbered prompt is a build with a deadline and a public write-up, so the work below was done in the open and graded by people who do this for a living.
An email-guessing function looked right on the first proof run until an independent recheck showed most of its answers were unprovable guesses.
What I sent
Since October I've had a 68-column Clay table that turns a name and a company domain into a verified email, a winner picked from ten patterns, each one checked against a live mailbox. Every new list meant rebuilding the column mapping by hand.
This time I built it as a function instead of a table: three required inputs in, one verified email out, published live in Clay so it drops into anyone's workspace without touching my original columns. What went out to the cohort was that function, a Loom walking through how it works, and the write-up built around the same 36-row test I used to catch my own bug.
The system
The validator I trust, Reoon, isn't one of Clay's 655 built-in actions, so the function reaches it with an HTTP call instead, the same way it would call any outside tool. Each pattern gets checked in the order it's most likely to be right: on 18,018 verified emails already in my database, first-initial-last covers 40 percent of real addresses, first.last another 26, first name alone another 20. Those three cover the overwhelming majority of what is guessable at all, so the waterfall tries them in that order and stops at the first one a live mailbox check actually confirms.
A waterfall moves on when a step comes back empty, but a validator always answers something, safe, catch-all, or invalid. So I built the relay that talks to Reoon to only hand back the email when the check says safe outright. Everything else, including catch-all, comes back empty on purpose, so the waterfall reads it as a miss and keeps going.
What changed between draft and send
The first proof run looked clean. I pulled 36 people from my own database, hid their real emails, fed the function just names and domains, and it answered 28 of them.
Before trusting any of it, I checked every answer straight against Reoon, outside Clay. Only 13 held up. The other 15 didn't: 14 sat on catch-all domains, the kind of address that says yes to anything you type in front of the @ sign, and one was flat wrong.
The bug was in how the function picked a winner. It skipped its own deep check whenever two validators agreed, and on a catch-all domain they always agree, so agreement got treated as proof.
The fix was simpler than the bug. Nothing wins now unless the live check says safe outright, and catch-all can't say that. Then I ran all 36 rows again from scratch, because a test you don't re-run after fixing what it tests doesn't prove anything.
The number that moved
Before the fix, the function answered 28 rows and only 13 of them were provable. After the fix, it answered 15, and all 15 held up against an independent recheck, zero catch-all, zero wrong. Fewer answers, but every one of them stands up outside my own pipeline.
Clay's own Work Email lookup answered 35 of the same 36 rows, more than double my recall, but only 21 of those 35 passed the same recheck, the other 14 catch-all guesses wearing a vendor database's coat. If your list lives in a database, their tool wins. If it doesn't, mine is for the person no database has.
What I'd change
The function still refuses on nicknames and middle initials. Patricia goes by patti, and right now that's a flat miss instead of a guess worth checking. I'd add a small table of common name variants so those rows get a real shot instead of an automatic pass.
I'd also run Work Email first as a cheap opening pass, and only send a row to my waterfall when the vendor lookup comes back empty or unprovable. Their database already knows who's in it. My waterfall should only spend a live mailbox check on the ones it doesn't.
guesser-build-receipts-20260823.mdopen, 22 lines
the first proof run was scored right and was lying about most of its answers
The audit that caught it, from the build receipts
## The audit that mattered
- v1 proof run (36 never-seen rows from agentic_leads, known emails held back):
  28 answers. Independent recompute straight against Reoon: 13 safe, 14 catch_all, 1 invalid.
  Root cause: consolidation skipped the deep check when both validators agreed, and on
  catch-all domains they always agree. Clay's native validate said mailbox_not_found on the
  spot-checked pick ([address]@mosscompany.com, sub_status mailbox_not_found, 1 credit).
- v2 fix published (Guess Status + Valid Email rebuilt; outputs re-declared because outputs
  bind to column identity, not name; "Review changes → 3 changes → Publish to function").
- v2 proof re-run, same 36 rows, full delete + re-insert: 15 answers, 15/15 independently
  re-verified deliverable, 0 catch-all, 0 wrong. 14/30 in-pattern exact matches to the
  year-old records, 1 different-but-valid (yusuf@ vs sabir@, same person). 21 refusals:
  13 catch-all domains (unverifiable by SMTP), 8 honest misses (nicknames Patricia/patti,
  Peter/pete; middle-initial sbstevens@; role inbox missionhills01@; 3 in-pattern the
  validators wouldn't confirm on the day).
## Cost, session total
| Meter | Before | After | Used |
|---|---|---|---|
| Clay credits | 39,548.8 | 39,387.8 | 161 (72 + 72 for the two 36-row runs, rest smoke/probes) |
| Reoon Agentic daily | 4,500 | 3,878 | 622 daily credits, 0 instant credits, $0 cash |
| Reoon Lumos | 4,500 daily | 4,500 | 0 (key swap verified) |
| Mailverify (template key) | unknown | unknown | ~800 calls, zero 402s/errors observed |
| Row ceiling (Erik: 100) | | | 80 used (6 smoke + 36 + 2 v2 test + 36 re-run), 20 left for Loom takes |
22 lines, the whole file. The section recording the first proof run and the fix. Read from agentic/alphaforge/prompt6/guesser-build-receipts-20260823.md at build time.
endpoint-test-receipts.mdopen, 7 lines
a guard built the same week fails loud instead of defaulting to clean when it can't read its own memory
The fail-closed checks, pass by pass
| baseline | clean lead answers `clean` | PASS |
| baseline | `memory_ok` true | PASS |
| canary broken | does NOT answer clean | PASS |
| canary broken | answers `error` | PASS |
| canary broken | `memory_ok` false | PASS |
| restored | answers `clean` again | PASS |
| restored | `memory_ok` true again | PASS |
7 lines, the whole file. Every row of the results table. Read from agentic/alphaforge/prompt6/endpoint-test-receipts.md at build time.
guesser/manual-step/waterfall-panel.png5 screenshots
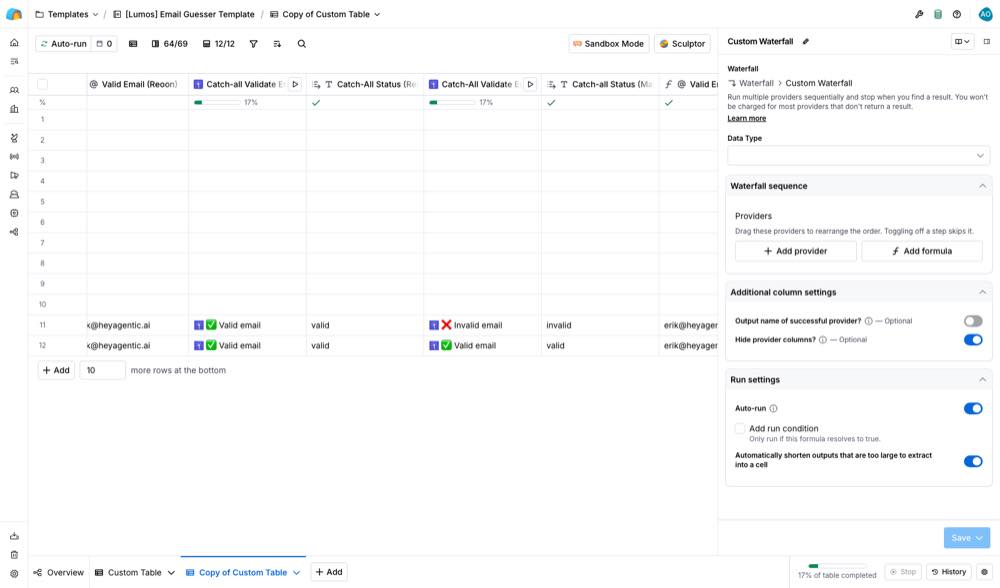
the native Waterfall column configuration as saved in Clay, the one step done by hand instead of the API